
Unlocking Extreme Performance: Inside Broadcom's Scale Up Ethernet Framework
Discover how SUE redefines high-speed connectivity for demanding AI and HPC workloads using specialized Ethernet.
The document you referenced, "Scale Up Ethernet Framework" (Specification: Broadcom Scale-Ethernet-RM101, dated May 1, 2025), details Broadcom's innovative approach to building highly efficient, low-latency networks specifically designed for connecting large clusters of XPUs (Accelerated Processing Units like GPUs, TPUs, or custom ML accelerators). This framework, known as Scale Up Ethernet (SUE), leverages the strengths of Ethernet while optimizing it for the unique demands of tightly coupled, high-performance computing environments like those used in Artificial Intelligence (AI), Machine Learning (ML), and High-Performance Computing (HPC).
Key Highlights of the SUE Framework
- Extreme Performance Focus: SUE prioritizes ultra-low latency (targeting sub-2 microsecond round-trip times) and massive bandwidth (up to 800 Gbps per instance, scalable higher) essential for memory-intensive operations between accelerators.
- Optimized Ethernet Base: It builds upon standard Ethernet components but employs specialized protocols, flow control (PFC/CBFC, LLR), and a simpler transport mechanism (Go-Back-N) tailored for lossless, high-throughput scale-up topologies, typically single-hop switched networks.
- Designed for Scale: The framework is engineered to interconnect up to 1024 XPUs efficiently within rack or multi-rack systems, supporting flexible port configurations (1x800G, 2x400G, 4x200G per instance) and multiple SUE instances per XPU for massive aggregate bandwidth (e.g., 9.6 Tbps between pairs of XPUs).
Why Scale Up Ethernet? Addressing the AI/HPC Challenge
The Need for Specialized Interconnects
Modern AI and ML workloads, particularly large model training and complex inference tasks, require unprecedented parallel processing power. This necessitates scaling XPU clusters significantly. However, simply connecting more accelerators isn't enough; the communication fabric between them becomes a critical bottleneck. Traditional networking solutions designed for general-purpose or scale-out data centers often introduce unacceptable latency or lack the sheer bandwidth required for tightly synchronized operations like collective communications or direct memory access across many devices.
SUE addresses this by creating a specialized network fabric based on Ethernet, benefiting from its mature ecosystem, high-speed links (200/400/800 Gbps+), and high-capacity switches. However, it adapts Ethernet specifically for the 'scale-up' domain, which involves densely packed accelerators communicating intensively within a limited physical area (like a rack or set of racks).
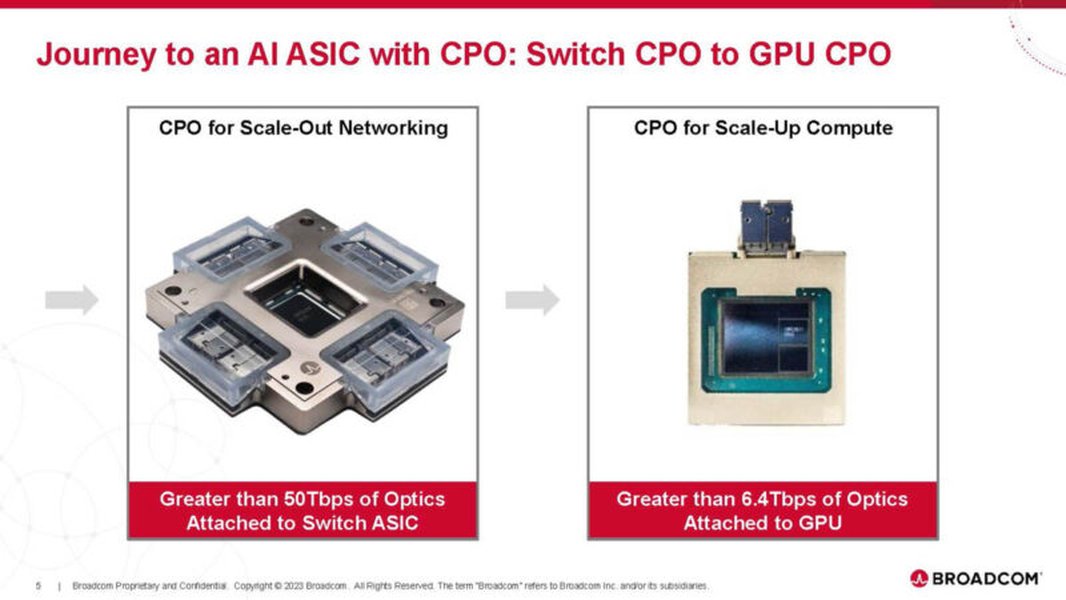
Conceptual diagram illustrating high-speed interconnects for AI ASICs, similar to the goals of the SUE framework.
Scale-Up vs. Scale-Out Requirements
The SUE specification explicitly differentiates the requirements of scale-up networks from scale-out networks:
- Scale-Up (SUE's Focus): Characterized by extremely high bandwidth demands between nodes, very low round-trip time (RTT) sensitivity, smaller node counts (up to ~1000), and typically simpler, often single-tier (single-hop switch) topologies. Reliability and low latency are paramount.
- Scale-Out (Traditional Data Centers): Often involves larger distances, higher node counts (tens of thousands), more complex multi-tier topologies, and different traffic patterns. While bandwidth is important, latency tolerances might be higher, and different transport protocols (like TCP or RoCEv2 over potentially lossy networks) are common.
SUE leverages the predictability and controlled environment of scale-up deployments to simplify the transport protocol, avoiding complex mechanisms like packet spraying or selective retransmission common in large scale-out fabrics, thereby reducing latency and implementation overhead.
Dissecting the SUE Architecture
Core Components and Functionality
The SUE framework defines a protocol stack and interfaces designed for efficient communication between an XPU's internal Network-on-Chip (NOC) and the external Ethernet network.
SUE Protocol Stack
The journey of a command from one XPU to another via SUE involves several steps:
- XPU Command Issuance: The source XPU's NOC sends a command (e.g., memory read, write, atomic operation) intended for a remote XPU via the SUE Command Interface.
- Mapping and Packing: A layer within SUE organizes commands based on their destination XPU and traffic class. It can pack multiple small commands into a single SUE Protocol Data Unit (PDU) for efficiency.
- Transport Layer Processing: SUE adds sequence numbers and prepares the PDU for reliable transmission. It interfaces with flow control mechanisms.
- Network Layer Encapsulation: The SUE PDU is mapped to a single Ethernet frame. The network layer constructs the necessary header (standard Ethernet or an optimized format) based on the destination.
- Link Layer Transmission: The frame is sent over the physical Ethernet port(s). Lossless operation is ensured using hardware-level flow control (PFC or CBFC) and Link-Level Retry (LLR) where available.
- Reception and Unpacking: At the destination, the receiving SUE instance verifies the Ethernet frame, unpacks the SUE PDU, checks for integrity, and handles acknowledgments.
- Command Delivery: The individual command(s) within the PDU are delivered to the destination XPU's NOC via its SUE Command Interface.
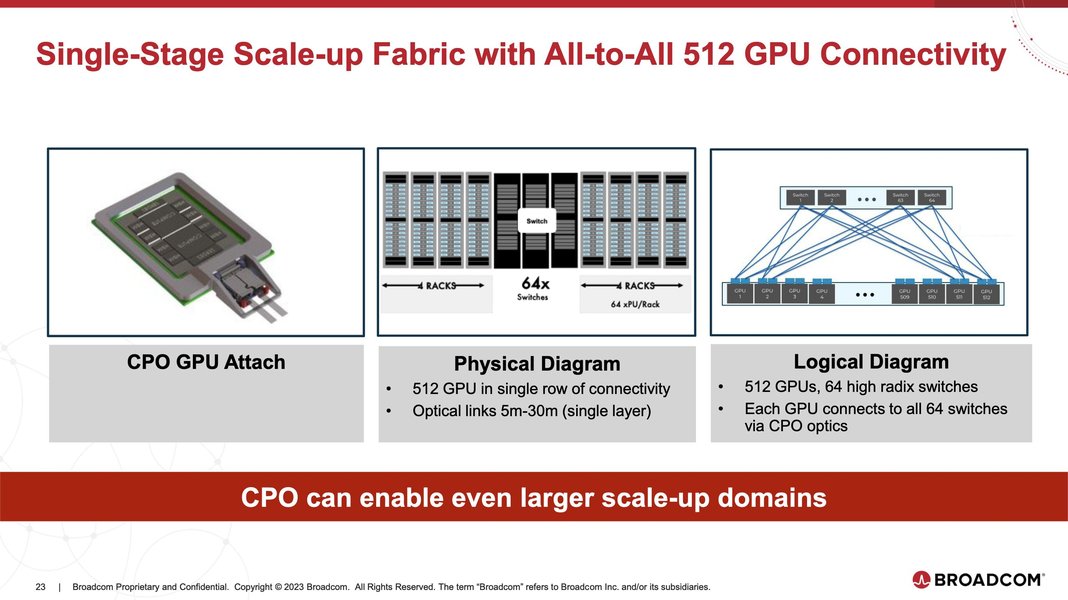
Illustration of a scale-up system architecture, highlighting the dense, high-bandwidth interconnects SUE is designed for.
Reliability and Flow Control
SUE mandates a lossless network environment between communicating XPUs. This is typically achieved using standard Ethernet features:
- Priority Flow Control (PFC): Allows pausing specific traffic classes to prevent buffer overflows without blocking other traffic.
- Credit-Based Flow Control (CBFC): An alternative mechanism for managing link bandwidth.
- Link-Level Retry (LLR): A feature in some Ethernet PHYs/switches that automatically retransmits corrupted packets at the physical link layer, reducing the burden on higher layers.
Even with these mechanisms, unrecoverable errors can occur. SUE implements a simple and efficient transport-level retransmission protocol based on **Go-Back-N**. This means if a packet is lost or corrupted beyond LLR's capability, the sender retransmits that packet and all subsequent packets sent on that specific virtual channel, ensuring in-order delivery within that channel. Connection state (like sequence numbers and acknowledgments) is maintained per physical port to manage this.
Ordering Modes
SUE supports two distinct ordering modes for transactions between a source and destination XPU:- Strict Ordering: Guarantees that all transactions arrive at the destination SUE transport in the exact order they were sent from the source SUE transport. This is crucial for algorithms sensitive to operation order.
- Unordered Mode: When an SUE instance uses multiple ports, this mode allows transactions to be load-balanced across these ports. While this maximizes bandwidth utilization, it does not preserve the original sending order. Order must be managed by the application or layers above SUE if required.
Command/Response Mechanism
SUE provides a generic mechanism for command/response transactions. The actual operations (like memory 'put', 'get', atomics, or custom XPU functions) are defined by the XPU vendor and are opaque to SUE itself. SUE simply transports these commands reliably. The XPU is responsible for mapping specific operations (e.g., a read request and its corresponding read response) to different traffic classes or virtual channels (VCs) if needed to manage priorities or prevent deadlocks.
SUE Interfaces
Connecting SUE to the System
Each SUE instance exposes three primary interfaces:
- XPU Command Interface: This is the high-performance data path. It's typically a FIFO-like interface using credits for flow control. Through this, the XPU sends commands (including destination ID, operation codes, data length, and payload) to SUE and receives incoming commands and responses from SUE. Flow control is managed per destination and per virtual channel.
- XPU Management Interface: An AXI (Advanced eXtensible Interface) target interface used for configuration, control, status monitoring, and register access of the SUE instance. It can also be used for low-rate, best-effort packet injection and reception, mainly for diagnostics.
- Ethernet Interface: The physical connection to the network. This interface comprises the Ethernet MAC (Media Access Control) and PHY (Physical Layer) components. It supports configurations of 1, 2, or 4 physical Ethernet ports per SUE instance, running at speeds like 200Gbps, 400Gbps, or 800Gbps per port, connecting SUE to Ethernet switches or directly to other XPUs in a mesh topology.
Deployment Scenarios and Performance Goals
Building High-Performance Clusters with SUE
Typical Topologies
- Single-Hop Switched: The preferred and most common topology. XPUs connect to one or more high-radix, low-latency Ethernet switches configured for lossless operation. This provides full non-blocking connectivity between all XPUs. A system with 64 XPUs, each having twelve 800G SUE instances, might connect via 12 separate 64-port 800G switches, enabling 9.6 Tbps aggregate bandwidth between any XPU pair.
- Mesh Topology: Direct XPU-to-XPU connections without switches. This might be used in smaller configurations or specific layouts but scaling becomes complex.
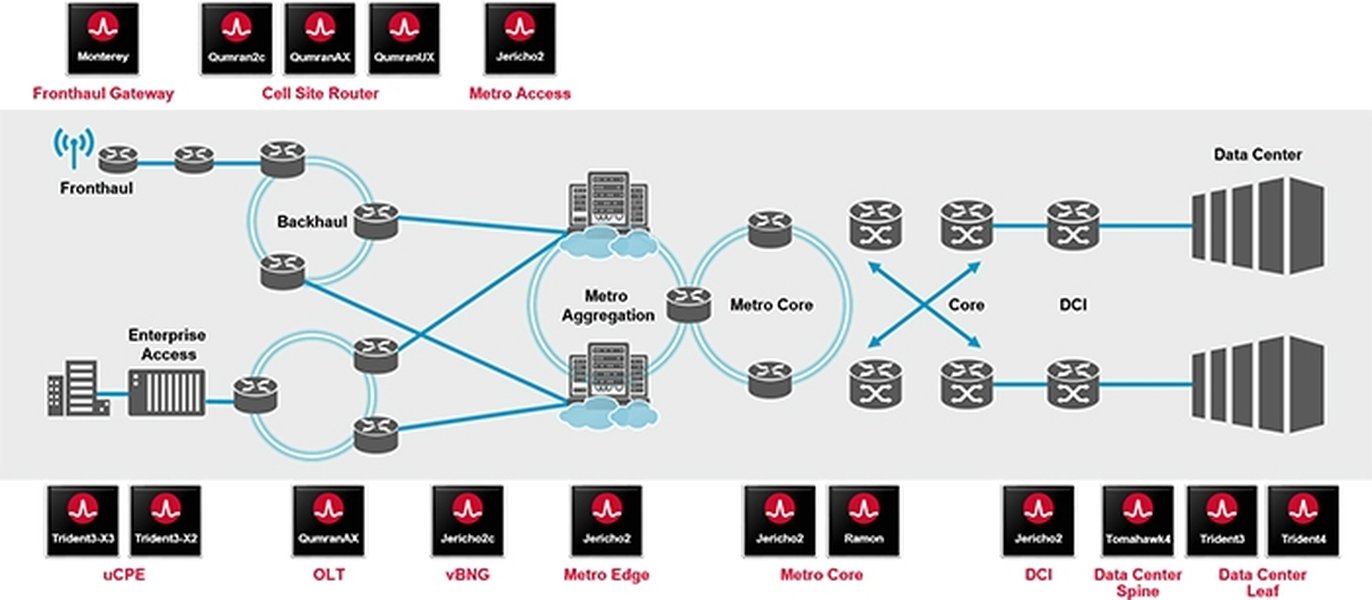
Broadcom's Ethernet switching solutions provide the high-radix, high-speed foundation needed for SUE deployments.
Performance and Scalability Targets
The SUE framework is designed with aggressive performance goals:
- Latency: End-to-end round trip latency (XPU-to-XPU) of less than 2 microseconds (µs).
- Bandwidth: 800 Gbps per SUE instance, scalable to 1.6 Tbps with future SerDes technology. Multiple instances per XPU multiply this significantly.
- Scalability: Designed to support clusters of up to 1024 XPUs within a single low-latency domain.
- Efficiency: Optimized for low area and power consumption on the XPU chip, allowing for multiple SUE instances per device.
- SerDes Support: Based on 200 Gbps SerDes lanes (also compatible with 100G/50G).
- Virtual Channels: Supports up to 4 VCs for traffic isolation and deadlock prevention.
SUE Performance Characteristics Compared
Visualizing SUE's Strengths
This chart provides a comparative overview of Scale Up Ethernet (SUE) against hypothetical standard Ethernet and a generic scale-out fabric when applied to the specific demands of AI accelerator interconnects. It highlights SUE's optimization for the critical factors in its target domain: low latency, high bandwidth within the scale-up cluster, protocol simplicity leading to efficiency, and overall scalability for its intended cluster size.
SUE Framework Structure Overview
Conceptual Mindmap
This mindmap illustrates the key conceptual areas covered by the Scale Up Ethernet framework specification, showing the relationships between its purpose, core features, interfaces, deployment models, and performance characteristics.
Interconnect (AI/ML/HPC)"] Goal1["Ultra-Low Latency (< 2µs RTT)"] Goal2["Massive Bandwidth (800Gbps+)"] Goal3["Efficient Scale-Up (≤ 1024 XPUs)"] KeyFeatures["Core Technical Aspects"] Feature1["Ethernet-Based Fabric"] Feature2["Lossless Operation (PFC/CBFC, LLR)"] Feature3["Simple Transport (Go-Back-N Retry)"] Feature4["Generic Command/Response"] Feature5["Ordering Modes (Strict/Unordered)"] Feature6["Optional Optimized Headers"] Feature7["Up to 4 Virtual Channels"] Interfaces["Connection Points"] IF1["XPU Command Interface (Data Plane)"] Detail1["FIFO-like, Credit-Based"] Detail2["Sends/Receives Commands & Data"] IF2["XPU Management Interface (Control Plane)"] Detail3["AXI Target"] Detail4["Configuration & Status"] IF3["Ethernet Interface (Network Plane)"] Detail5["1, 2, or 4 Ports per Instance"] Detail6["200G/400G/800G Speeds"] Detail7["MAC/PHY Layer"] Deployment["Network Topologies"] Dep1["Single-Hop Switched (Primary)"] Dep2["Mesh (Alternative)"] Performance["Design Goals & Efficiency"] Perf1["Target Specifications (Latency, BW)"] Perf2["Focus on Power/Area Efficiency"] Perf3["Leverages 200G SerDes"]
Key SUE Specifications Summary
At-a-Glance Technical Details
The following table summarizes the core technical specifications and requirements outlined in the SUE framework document:
| Feature / Requirement | Specification / Target |
|---|---|
| Target Application | AI/ML/HPC XPU Scale-Up Interconnect |
| Primary Topology | Single-Hop Switched Ethernet |
| Max Supported XPUs | Up to 1024 |
| Target End-to-End RTT Latency | < 2 microseconds (µs) |
| Bandwidth per SUE Instance | 800 Gbps (Scalable to 1.6 Tbps) |
| Ethernet Port Speeds | 200 Gbps, 400 Gbps, 800 Gbps |
| Ports per SUE Instance | 1, 2, or 4 |
| SerDes Technology | 200 Gbps (supports 100G, 50G) |
| Supported Transactions | Generic Command/Response (e.g., Memory Put/Get/Atomics) |
| Memory Model Assumption | Shared Memory (PGAS-like) |
| Network Operation | Lossless (Requires PFC or CBFC) |
| Link Layer Reliability | Link Level Retry (LLR) where available |
| Transport Layer Reliability | Go-Back-N Retransmission |
| Ordering Modes | Strict Ordering OR Unordered (Load Balanced) |
| Virtual Channels (VCs) | Up to 4 |
| Header Format | Standard Ethernet or Optimized/Compressed options |
| Key Design Focus | Low Latency, High Bandwidth, Power/Area Efficiency |
Visualizing Ethernet in Scale-Up Networks
Perspectives on High-Performance Ethernet
The following video from the OCP Summit 2024 discusses the role and evolution of Ethernet in building scale-up networks, similar to the domain targeted by Broadcom's SUE framework. It provides broader industry context on using Ethernet technologies for high-performance, low-latency communication fabrics required by demanding workloads like AI training clusters.
OCP Summit 2024 presentation discussing Ethernet's path towards scale-up networking solutions.
Frequently Asked Questions (FAQ)
Quick Answers about SUE
What is the main purpose of the Scale Up Ethernet (SUE) framework?
How is SUE different from standard Ethernet or RoCE?
What are the key benefits of using SUE?
What kind of operations does SUE transport?
Recommended Reading & Exploration
Dive Deeper into Related Topics
- How does Broadcom SUE compare to NVIDIA NVLink or InfiniBand for AI clusters?
- What are the implementation details of SUE's Go-Back-N transport protocol?
- Which specific GPUs or AI accelerators currently support the Broadcom SUE framework?
- What is the role of lossless Ethernet configurations like PFC and LLR in enabling SUE?
References
Last updated May 4, 2025