
Empowering Your Enterprise: A Guide to Developing and Deploying Private LLMs
Unlocking Tailored AI Solutions with In-House Large Language Models
Key Insights into Private LLM Implementation
- Strategic Imperative: Developing a private Large Language Model (LLM) allows businesses to gain a competitive edge by leveraging proprietary data, ensuring enhanced security, and achieving highly customized AI capabilities that public models cannot offer.
- Tailored Solutions and Data Privacy: Private LLMs are built on an organization's specific data and goals, providing greater control over sensitive information, fostering data security, and enabling responses that are directly relevant to unique business needs and industry contexts.
- Deployment Flexibility: Enterprises can choose from various deployment strategies, including fine-tuning existing open-source models, utilizing Retrieval-Augmented Generation (RAG), or, in rarer cases, building an LLM from scratch, with options for on-premises, cloud, or hybrid infrastructure.
In today's rapidly evolving digital landscape, the concept of Large Language Models (LLMs) has captivated businesses across industries. While widely accessible public LLMs like ChatGPT offer remarkable capabilities, many organizations are exploring the strategic advantages of developing and deploying their own private LLMs. A private LLM, also known as a company-specific or proprietary LLM, is an AI model developed and owned by a specific company, trained on its internal data and resources. This approach provides unparalleled control, customization, and security, allowing businesses to unlock actionable insights and create truly tailored AI solutions.
The Strategic Rationale for a Company-Specific LLM
The decision to invest in a private LLM is a strategic one, driven by several compelling benefits that address the limitations of generic, public models. While public LLMs are convenient and readily available, they are trained on general datasets and may not fully capture the unique context, language, or specific needs of a particular business or industry. Furthermore, relying on public models can raise significant concerns regarding data privacy and security, as sensitive company information might be exposed to third parties.
Unlocking Customization and Relevance
One of the primary advantages of a private LLM is the ability to achieve a high degree of customization. By training the model on domain-specific data—such as internal documentation, customer feedback, product reviews, and proprietary knowledge bases—businesses can ensure that the LLM generates highly relevant and accurate responses tailored to their unique operations and industry jargon. This level of precision can lead to better, more relevant outputs that boost customer satisfaction and loyalty, and streamline internal workflows.
Ensuring Data Privacy and Security
For organizations handling sensitive data, such as those in healthcare or finance, data privacy and compliance with regulations like GDPR and HIPAA are paramount. Public LLMs, while powerful, often operate on external servers, which can introduce potential security vulnerabilities and data exposure risks. A private LLM, deployed on an organization's own infrastructure or a private cloud, allows for complete control over data handling and processing protocols. This mitigates the risks associated with sharing proprietary information with external models, ensuring the confidentiality of sensitive data.
Gaining Competitive Differentiation and Intellectual Property
Building a custom LLM can significantly differentiate a business from its competitors. By leveraging proprietary data to train the model, companies create a unique AI asset that understands their customers, industry, and brand in a way that generic models cannot. This intellectual property can open up new opportunities for licensing, patents, or even the creation of novel AI-powered products and services, fostering innovation and maintaining a competitive edge.
Achieving Long-Term Cost Efficiency
While the initial investment in building a private LLM can be substantial, it can lead to long-term cost efficiencies. By owning the entire infrastructure and model, businesses can eliminate recurring usage fees associated with third-party LLM providers. This allows for better cost control, especially as the business scales and AI usage increases, making it a more sustainable solution over time.
Approaches to Developing Your Own LLM
Developing a company-specific LLM involves a spectrum of approaches, ranging from leveraging existing open-source models to, in rare cases, building an LLM from scratch. The choice depends on the organization's resources, technical expertise, specific needs, and desired level of control.
Fine-Tuning Open-Source Models
For most businesses, fine-tuning an existing open-source LLM is the most practical and efficient approach. This involves taking a pre-trained model (like LLaMA, Mistral, or Falcon) and adapting it to specific business use cases by training it further on a smaller, domain-specific dataset. This method saves significant time and money compared to building an LLM from scratch, as the foundational language understanding is already in place. The process typically includes:
- Selecting an Open-Source LLM Framework: Choose a foundational model that aligns with your objectives and technical capabilities.
- Collecting and Processing Domain-Specific Data: Gather relevant internal documents, customer interactions, product information, and other proprietary text data. This data needs to be cleaned, preprocessed, and formatted for training.
- Training (Fine-Tuning) the Model: Use high-performance compute clusters (GPUs or TPUs) to fine-tune the chosen open-source model on your processed data. This step adapts the model's knowledge to your company's unique context.
- Parameter Optimization: Apply techniques to optimize the model's parameters to meet specific business goals and performance metrics.
Companies like Databricks have demonstrated the effectiveness of this approach with models like Dolly, designed to follow instructions after being trained on specific datasets and licensed for commercial use.
Retrieval-Augmented Generation (RAG)
Retrieval-Augmented Generation (RAG) is a powerful technique that enhances the capabilities of existing LLMs without requiring full model retraining. Instead of solely relying on the LLM's pre-trained knowledge, RAG systems retrieve relevant information from an external, proprietary knowledge base and use it to inform the LLM's responses. This is particularly useful for providing up-to-date information or non-public data. Key steps involve:
- Building a Knowledge Base: Organize your company's documents and data into a structured knowledge base, often using vector databases.
- Embedding Documents: Convert documents into numerical embeddings that can be quickly searched and retrieved.
- Integrating with an LLM: When a user query is received, the RAG system first retrieves the most relevant information from your knowledge base and then passes this context to the LLM, enabling it to generate more accurate and informed responses.
Building an LLM from Scratch
Building an LLM from scratch is the most resource-intensive and complex approach, typically reserved for organizations with significant AI expertise, substantial budgets, and very niche requirements that cannot be met by existing models. This involves:
- Defining Objectives and Requirements: Clearly outline the specific tasks and functionalities the LLM needs to perform.
- Massive Data Collection and Preprocessing: Acquire and meticulously prepare vast amounts of text data from diverse sources, ensuring it is clean, relevant, and representative of the desired language patterns.
- Model Architecture Design: Develop the neural network architecture, often based on transformer models, from the ground up.
- Extensive Training: Train the model on massive compute clusters over extended periods, requiring significant computational resources (GPUs/TPUs) and electricity.
- Evaluation and Iteration: Continuously evaluate the model's performance, identify biases, and iterate on the training process.
This path is fraught with challenges, including high costs, the need for specialized talent (NLP, data science, software engineering), and a long development timeline (potentially 2-3 years).
Essential Steps for Enterprise LLM Deployment
Once a private LLM is developed or fine-tuned, its effective deployment in a production environment is crucial for realizing its business value. This process requires careful planning and execution to ensure reliability, scalability, and maintainability.
Defining Clear Objectives and Use Cases
Before deployment, clearly define what the LLM will be used for. Specific use cases, such as internal chatbots for IT instructions, customer support agents for product inquiries, or tools for data analysis and report generation, will guide decisions on model choice, deployment architecture, and performance metrics. The problem should be focused enough to deliver quick impact but also significant enough to truly benefit users.
Infrastructure and Environment Setup
The computational demands of LLMs are substantial. Organizations must determine the appropriate infrastructure: on-premises data centers, cloud services, or a hybrid approach. This involves:
- Hardware Sizing: Assess the GPU memory and processing power required to serve the model at scale, considering concurrent requests and potential failover systems. Nvidia's support matrix can offer guidance here.
- Software Installation: Set up the necessary software environment, including Python, deep learning frameworks (e.g., PyTorch, TensorFlow), and serving frameworks (e.g., OpenLLM, Ray Serve, Hugging Face).
- Environment Configuration: Configure the deployment environment, whether bare metal, virtual machines, or containerization platforms like Docker and Kubernetes. Kubernetes is often preferred for large-scale deployments due to its ability to automate container creation, networking, and load balancing.
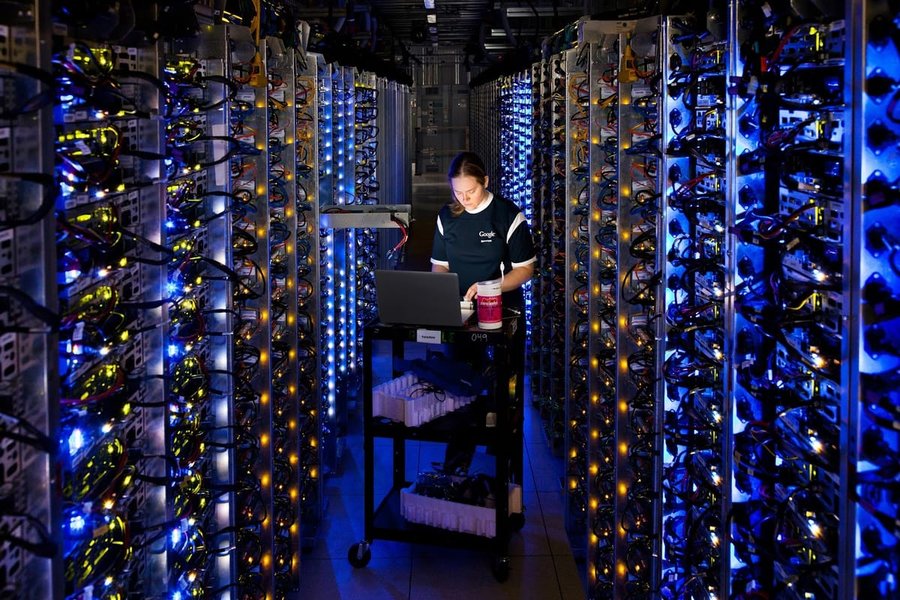
Modern data center infrastructure, crucial for LLM deployment.
Data Integration and Knowledge Base Development
For fine-tuned models or RAG systems, the ability to integrate with internal company data is critical. This involves:
- Data Collection and Preprocessing: Continuously gather, clean, and transform diverse data types (structured, semi-structured, unstructured) essential for LLM training and RAG. Tools like Airbyte can facilitate this process.
- Knowledge Base Construction: Build and maintain a robust knowledge base, often leveraging vector databases, to store and retrieve relevant information for the LLM.
- Data Security and Compliance: Implement encryption, access control mechanisms, and ensure compliance with all relevant data privacy regulations to protect sensitive business and customer data.
Model Serving and Performance Optimization
Deploying an LLM means making it accessible for applications to use, often through an API. This stage focuses on performance, scalability, and cost management:
- API Integration: Expose the LLM functionality via an OpenAI-compatible API for seamless integration with internal applications.
- Performance Tuning: Optimize the model for speed, especially under heavy loads, using strategies like model compression, efficient serving frameworks, and potentially offloading some processing tasks to edge devices.
- Scalability: Design the deployment to scale horizontally to handle future growth and varying request volumes.
- Cost Control: Balance performance with cost efficiency by optimizing resource allocation, using cost-effective cloud services, and regularly reviewing usage patterns.
Monitoring, Evaluation, and Continuous Improvement
LLM deployment is not a one-time event; it's an ongoing process. Continuous monitoring and evaluation are essential for maintaining model performance, addressing issues, and adapting to evolving business needs:
- Performance Monitoring: Implement automated monitoring of LLM responses against defined metrics, observing latency, throughput, and accuracy.
- Prompt Management: Experiment with different prompts and systematically refine them based on the LLM's responses. Tools like Langfuse can help manage prompt templates and versioning.
- CI/CD Pipeline: Develop a Continuous Integration/Continuous Deployment (CI/CD) pipeline for the LLM application to automate testing, deployment, and model updates.
- Guardrails and Safety: Implement mechanisms to ensure the LLM generates safe, ethical, and unbiased responses, particularly for sensitive applications.
The following radar chart illustrates a comparative analysis of key considerations when deciding to build or buy an LLM solution. This chart is based on general industry observations and typical enterprise priorities, providing a visual representation of the trade-offs involved in each approach.
The radar chart above visualizes the strengths and weaknesses of different LLM acquisition strategies for enterprises. "Building Your Own LLM (Private)" typically scores highest on data privacy, customization, and control over intellectual property, but lower on initial cost and time to market due to the extensive resources required. "Using a Public LLM (Proprietary APIs)" excels in time to market and often lower initial costs, but sacrifices data privacy, customization, and control. "Fine-tuning Open-Source LLM" presents a balanced approach, offering a good compromise between privacy, customization, and feasibility for many organizations.
Understanding Key LLM Development & Deployment Considerations
The journey of deploying an LLM for enterprise use comes with a set of critical considerations that impact its success and long-term viability.
The "Build vs. Buy" Dilemma
The fundamental choice for enterprises is between using a third-party LLM service (buying) or developing an in-house solution (building). While commercial LLMs offer quick deployment and convenience, they may not deliver the niche performance required for highly specific business problems. Building or fine-tuning provides deep customization and strategic differentiation.
Addressing Privacy and Compliance
For many industries, data privacy and regulatory compliance (e.g., GDPR, HIPAA) are non-negotiable. Using a private LLM deployed within an organization's secure infrastructure can eliminate concerns about third-party data exposure, which is a major deterrent for businesses considering proprietary LLMs from external vendors.
Computational Resources and Cost
LLMs are computationally intensive. Running models locally or in a private cloud environment requires significant hardware investment (high-end GPUs, ample memory) and ongoing operational costs for power and cooling. The scale of these resources varies dramatically based on the model size and the expected workload. While the upfront costs for building or self-hosting can be high, they may be offset by avoiding recurring usage fees from public API providers in the long run, particularly as usage scales.
AI data centers are the backbone of modern LLM deployments.
Talent and Expertise
Developing and deploying an LLM, even through fine-tuning, requires a specialized team with expertise in NLP, data science, machine learning engineering, and MLOps (Machine Learning Operations). Organizations need to ensure they have access to or can acquire this talent to manage the complexity of data preparation, model training, optimization, and continuous monitoring.
Avoiding Vendor Lock-in
Building a private LLM reduces reliance on specific service providers. This offers greater control over the technology stack and allows the organization to magnify or enhance components as needed, without being tied to a particular vendor's ecosystem or pricing structure.
Deployment Strategies in Detail
Enterprises can choose from various deployment strategies, each with distinct benefits and challenges. The selection should align with the organization's specific use case, security requirements, and technical capabilities.
Cloud-Based Deployment
Many organizations opt to deploy LLMs on cloud platforms (e.g., AWS, Azure, Google Cloud) due to their scalability, managed services, and access to powerful GPUs. This can involve:
- Managed LLM Services: Utilizing platform-specific services that abstract away much of the infrastructure management.
- Virtual Machines/Containers: Deploying models on virtual machines or containerized environments (like Kubernetes) for more control over the stack.
On-Premises Deployment
For maximum data control and security, especially in highly regulated industries, some enterprises choose to deploy LLMs on their own private servers within their data centers. This requires significant upfront investment in hardware and expertise to manage the infrastructure, but ensures complete data sovereignty.
Hybrid Deployment
A hybrid approach combines the benefits of both cloud and on-premises environments. For instance, sensitive data processing might occur on-premises, while less sensitive tasks leverage cloud scalability. This strategy allows organizations to balance control, cost, and flexibility.
Key Components of an LLM Application Pipeline
Regardless of the deployment strategy, an enterprise-grade LLM application typically involves several interconnected components:
| Component | Description | Relevance to Private LLM |
|---|---|---|
| Data Ingestion & Preprocessing | Collecting, cleaning, and transforming diverse internal data (text, documents, databases) into a format suitable for model training or retrieval. | Crucial for tailoring the LLM to proprietary knowledge and ensuring data quality. |
| Knowledge Base (Vector Database) | Storing embedded representations of proprietary data for efficient retrieval in RAG architectures. | Enables LLMs to access and utilize up-to-date, company-specific information without retraining. |
| LLM Core (Fine-tuned/Custom Model) | The actual language model, either fine-tuned from an open-source base or custom-built, responsible for understanding and generating text. | The heart of the private LLM, embodying its specialized knowledge and capabilities. |
| Serving Layer (API Gateway) | Exposing the LLM functionality via APIs for integration with enterprise applications and user interfaces. | Allows internal applications and employees to easily interact with the private LLM. |
| Monitoring & Observability | Tracking model performance, latency, accuracy, and resource utilization in real-time. | Essential for maintaining model health, identifying issues, and ensuring optimal operation. |
| Security & Governance | Implementing access controls, encryption, and compliance measures to protect data and ensure ethical AI use. | Fundamental for sensitive data, ensuring the private LLM adheres to company policies and regulations. |
| Feedback & Retraining Pipeline | Collecting user feedback and new data to continuously improve and update the LLM over time. | Enables the LLM to learn and adapt to evolving business needs and new information. |
This table highlights the foundational elements necessary for robust LLM deployment within an enterprise, emphasizing the importance of each stage in creating a secure, efficient, and highly relevant private AI solution.
Understanding the "Why" and "How" of Private LLMs
The following video provides practical insights into implementing private LLMs for in-house AI solutions. It offers a fundamental understanding of LLMs and how their private versions can be leveraged within an organization.
Implementing Private Large Language Models for In-House AI Solutions - Practical Overview
The video delves into the practical aspects of implementing private LLMs, covering key considerations such as data handling, model customization, and deployment strategies. It helps demystify the process for businesses looking to bring AI capabilities in-house while maintaining control over their data and intellectual property. This resource is particularly valuable for understanding the operational realities and technical nuances involved in transitioning from theoretical understanding to practical application of private LLMs within an enterprise setting.
Future Trends in Private LLMs
The landscape of private LLMs is continuously evolving. Future trends indicate a move towards more accessible and robust solutions:
- Increased Adoption of Open-Source Models: The growing maturity and performance of open-source LLMs (like LLaMA 2, Mistral) make them increasingly viable foundations for private enterprise solutions, reducing reliance on proprietary models.
- Enhanced Security and Privacy Features: Continued development in privacy-preserving AI techniques will further strengthen the security of private LLMs, addressing concerns around sensitive data.
- Integration with Enterprise Systems: Deeper and more seamless integration of private LLMs into existing enterprise workflows and applications will become a standard, enhancing operational efficiency.
- Edge AI and Local Deployment: As models become more efficient, the ability to run LLMs locally on smaller, dedicated hardware at the "edge" will gain traction, offering even greater control and reduced latency for specific use cases.
- Multimodal Capabilities: Future private LLMs will increasingly incorporate multimodal AI, combining language understanding with visual comprehension to interpret and generate content that integrates both textual and visual elements, offering a more comprehensive user experience.
Frequently Asked Questions (FAQ)
What is a private LLM?
Why would a company build its own LLM instead of using public ones?
Is it necessary to build an LLM from scratch?
What are the key steps in deploying a private LLM?
What are the main challenges in deploying an LLM in an enterprise?
Conclusion
Having your own Large Language Model as a company is a strategic move that offers significant advantages in customization, data privacy, and competitive differentiation. While it presents challenges in terms of resources, expertise, and infrastructure, the ability to tailor an AI to your unique business needs and ensure the confidentiality of sensitive information can lead to transformative outcomes. By carefully considering the various development and deployment approaches, from fine-tuning open-source models to implementing RAG architectures, organizations can embark on a successful journey towards empowering their operations with proprietary AI.
Recommended Further Reading
- How to select the right LLM architecture for enterprise needs?
- What are the best practices for data security in private LLM deployments?
- Perform a cost-benefit analysis of private vs. public LLMs for businesses.
- Explore the critical role of MLOps in managing enterprise LLMs effectively.
References
Last updated May 21, 2025