
Calculating the Mean Deviation for Grouped Data
Understanding the steps for computing variability in grouped data
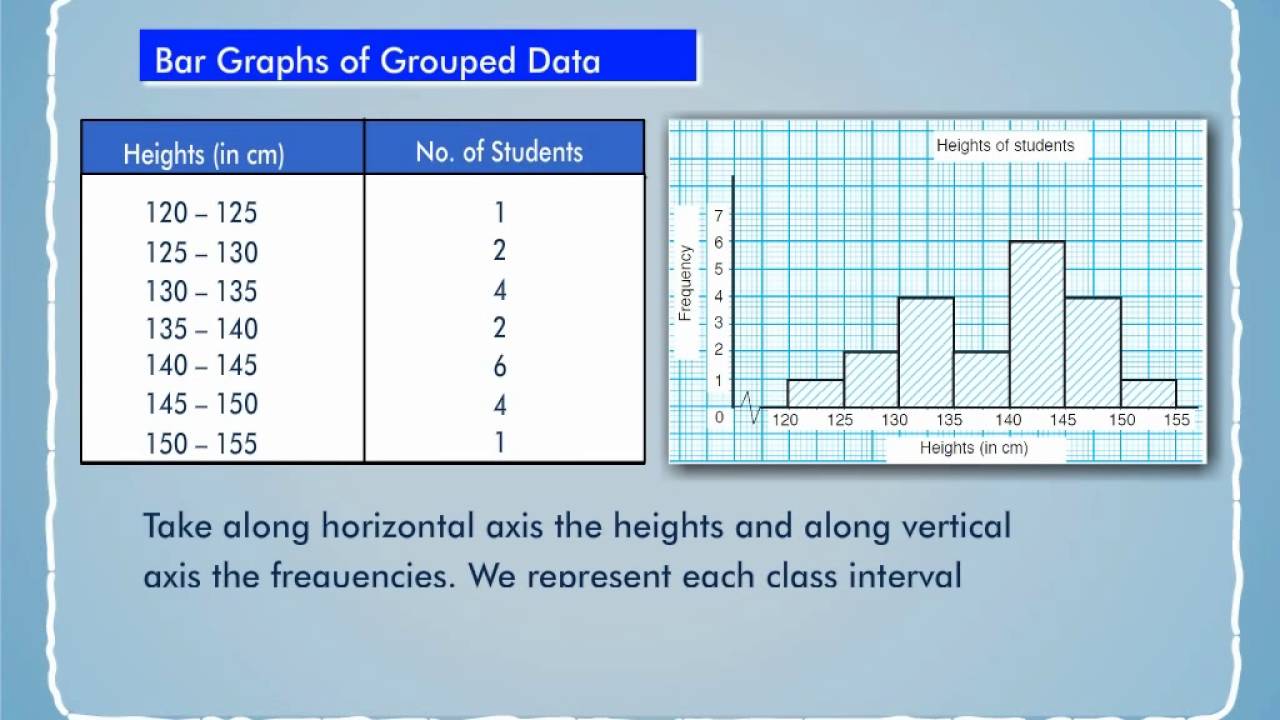
Key Insights
- Grouping Data: Grouped data organizes observations into classes, making calculations rely on class midpoints and frequencies.
- Step-by-Step Process: The method includes computing class midpoints, finding the overall mean, determining absolute deviations, and finally averaging these deviations weighted by their frequencies.
- Purpose and Utility: Mean deviation (or mean absolute deviation, MAD) provides a clear measure of variability which is easier to interpret than variance or standard deviation in some contexts.
Introduction
Calculating the mean deviation for grouped data is a key statistical task used to assess the dispersion or variability within a data distribution when individual data points are not available but instead are summarized into classes. The process is particularly useful in situations where the data is grouped into intervals, such as age ranges, income brackets, or test score ranges.
Understanding the Concepts
Grouped Data
Grouped data refers to a frequency distribution that aggregates individual data points into intervals, or classes. Each class has an associated frequency representing the number of observations that fall within that range. Instead of having detailed values, we work with summary representations where the central tendency of each class is approximated by its midpoint.
Mean Deviation (MAD)
The mean deviation, often referred to as the mean absolute deviation (MAD), is a measure of the average distance between each data point (or in grouped data, the midpoint of each class) and a central value, typically the mean of the distribution. It gives a straightforward interpretation of variability.
Step-by-Step Calculation Procedure
Step 1: Identify Classes and Frequencies
Begin by organizing the data into classes or intervals and noting the frequency of each class. The classes represent the range of values, and the frequencies indicate how many observations are in each class.
Step 2: Calculate the Midpoints
Definition and Formula
The midpoint (or class mark) is the average of the lower and upper limits of a class interval. The formula for the midpoint \( \text{\(x_i\)} \) of the ith class is:
\( \displaystyle x_i = \frac{\text{Lower Limit} + \text{Upper Limit}}{2} \)
This value represents a typical observation within that class.
Step 3: Compute the Mean of the Grouped Data
Calculation Process
To compute the mean \( \overline{x} \) of the data, multiply each class midpoint \( x_i \) by the corresponding frequency \( f_i \), sum all these products, and then divide by the total frequency \( N \):
\( \displaystyle \overline{x} = \frac{\sum (f_i \cdot x_i)}{\sum f_i} \)
Step 4: Calculate Absolute Deviations
Absolute Deviations from the Mean
For each class, compute the absolute deviation by subtracting the overall mean from the class midpoint and taking the absolute value:
\( \displaystyle |x_i - \overline{x}| \)
This value quantifies how far, on average, the midpoint is from the central mean.
Step 5: Weight the Deviations by Their Frequencies
Multiplying by Frequency
Multiply the absolute deviation for each class by its frequency in order to account for the significance of each interval in the overall data set:
\( \displaystyle f_i \cdot |x_i - \overline{x}| \)
Step 6: Compute the Mean Deviation
Final Calculation
Sum the weighted absolute deviations across all classes and divide by the total frequency to reach the mean deviation:
\( \displaystyle \text{Mean Deviation} = \frac{\sum (f_i \cdot |x_i - \overline{x}|)}{\sum f_i} \)
This formula provides the overall average deviation from the mean for the grouped data.
Example Calculation
Sample Data Set
Consider a data set grouped into the following classes:
| Class Interval | Frequency \( f_i \) |
|---|---|
| 10 - 14 | 5 |
| 15 - 19 | 2 |
| 20 - 24 | 19 |
| 25 - 29 | 4 |
| 30 - 34 | 18 |
| 35 - 39 | 2 |
Calculation Details
Step 1: Compute Midpoints
Calculate the midpoint \( x_i \) for each interval:
- 10-14: \( x_i = \frac{10 + 14}{2} = 12 \)
- 15-19: \( x_i = \frac{15 + 19}{2} = 17 \)
- 20-24: \( x_i = \frac{20 + 24}{2} = 22 \)
- 25-29: \( x_i = \frac{25 + 29}{2} = 27 \)
- 30-34: \( x_i = \frac{30 + 34}{2} = 32 \)
- 35-39: \( x_i = \frac{35 + 39}{2} = 37 \)
Step 2: Compute the Mean \( \overline{x} \)
Next, calculate the product \( f_i \times x_i \) for each class:
| Class Interval | Midpoint \( x_i \) | Frequency \( f_i \) | Product \( f_i \times x_i \) |
|---|---|---|---|
| 10-14 | 12 | 5 | 60 |
| 15-19 | 17 | 2 | 34 |
| 20-24 | 22 | 19 | 418 |
| 25-29 | 27 | 4 | 108 |
| 30-34 | 32 | 18 | 576 |
| 35-39 | 37 | 2 | 74 |
The sum of the products is:
\( \displaystyle \sum (f_i \cdot x_i) = 60 + 34 + 418 + 108 + 576 + 74 = 1270 \)
The sum of the frequencies is:
\( \displaystyle \sum f_i = 5 + 2 + 19 + 4 + 18 + 2 = 50 \)
Thus, the mean is:
\( \displaystyle \overline{x} = \frac{1270}{50} = 25.4 \)
Step 3: Calculate Absolute Deviations
For each class, compute the absolute difference between the midpoint and the mean:
- For 10-14: \( |12 - 25.4| = 13.4 \)
- For 15-19: \( |17 - 25.4| = 8.4 \)
- For 20-24: \( |22 - 25.4| = 3.4 \)
- For 25-29: \( |27 - 25.4| = 1.6 \)
- For 30-34: \( |32 - 25.4| = 6.6 \)
- For 35-39: \( |37 - 25.4| = 11.6 \)
Step 4: Multiply Absolute Deviations by Frequencies
Next, weight the absolute deviations by the class frequencies:
- 10-14: \( 5 \times 13.4 = 67 \)
- 15-19: \( 2 \times 8.4 = 16.8 \)
- 20-24: \( 19 \times 3.4 = 64.6 \)
- 25-29: \( 4 \times 1.6 = 6.4 \)
- 30-34: \( 18 \times 6.6 = 118.8 \)
- 35-39: \( 2 \times 11.6 = 23.2 \)
Sum these values:
\( \displaystyle \sum (f_i \cdot |x_i - \overline{x}|) = 67 + 16.8 + 64.6 + 6.4 + 118.8 + 23.2 = 296.8 \)
Step 5: Final Computation of Mean Deviation
Finally, the mean deviation is computed by dividing the sum of the weighted deviations by the total frequency:
\( \displaystyle \text{Mean Deviation} = \frac{296.8}{50} = 5.936 \)
The result, 5.936, represents the average distance of the class midpoints from the overall mean.
Additional Considerations and Practical Applications
Interpreting Results
The mean deviation provides a simple yet effective measure of dispersion. It is particularly useful in cases where understanding the average absolute error or variation from a central tendency is more intuitive than concepts like variance, which involves squaring deviations. By using the absolute differences, you avoid the complexity introduced by negative deviations canceling out positive ones.
Moreover, in contexts such as quality control, finance, or everyday statistical analysis, the mean deviation can quickly inform how spread out your data is, helping to identify consistency or volatility within the dataset.
When to Use Mean Deviation
Practical Applications
Mean deviation is widely applied in various fields including:
- Economics: Understanding income distributions or price fluctuations.
- Education: Analyzing test scores where data is grouped into scoring intervals.
- Quality Assurance: Detecting consistency in production processes.
- Research: Presenting data variability where a simpler interpretation is valuable.
Comparisons with Other Measures
While measures such as variance and standard deviation are common, mean deviation offers an alternative that can be easier to comprehend. Variance and standard deviation square or take square roots of differences, which can make the units of measurement less intuitive. Mean deviation, maintaining the original units, is especially relevant for non-technical presentations and initial exploratory data analysis.
References
- Grouped Data Standard Deviation Calculator - Ncalculators
- How to Find Mean & Standard Deviation of Grouped Data - Statology
- Mean Deviation For Grouped Data - BYJU'S
- Mean Deviation for Grouped Data - fhybea
- Mean Deviation: Definition, Formula, Examples, and FAQs - GeeksforGeeks
Recommended Searches
Last updated March 12, 2025