
Unlock Real-Time Multimodal Conversations: Your Guide to Using the Google Gemini Live API
Dive into building dynamic applications with live voice, video, and text interactions powered by Gemini.
The Google Gemini Live API opens up exciting possibilities for creating applications that engage users in natural, real-time conversations. This powerful API supports low-latency, bidirectional interactions, processing text, audio, and video inputs to deliver intelligent text and audio responses. Whether you're aiming to build advanced virtual assistants, interactive customer support bots, or innovative multimodal experiences, this guide will walk you through the essentials of leveraging the Gemini Live API.
Key Highlights of the Gemini Live API
- Real-Time Bidirectional Communication: Utilizes WebSocket connections for continuous, low-latency data exchange, enabling fluid conversations.
- Rich Multimodal Capabilities: Processes a combination of text, audio, and video inputs, and can generate both text and high-quality synthesized audio outputs.
- Server-Side Integration: Designed primarily for server-to-server authentication and implementation, ensuring secure and robust application backends.
Getting Started: Prerequisites
Before you can harness the power of the Gemini Live API, you'll need a few things in place:
1. Google Cloud Account and Project
You must have an active Google Cloud account. If you don't have one, you can sign up on the Google Cloud Console. Within your account, create a new Google Cloud project or select an existing one. This project will house your API credentials and manage billing.
2. Enable the API
Ensure that the Vertex AI API or the Gemini API service is enabled for your Google Cloud project. You can do this through the Google Cloud Console by navigating to the API Library and searching for the relevant service.
3. Obtain an API Key
An API key is crucial for authenticating your requests. You can generate an API key through Google AI Studio or the Google Cloud Console for your project. Store this key securely, as it grants access to the API.
Obtaining an API Key is a crucial first step.
4. Programming Environment
Choose a supported programming language. Python is commonly used for backend development with Gemini. The Google AI JavaScript SDK is also available, often used for web-based prototyping, but remember that the Live API is recommended for server-side use due to its authentication model.
Setting Up Your Development Environment
Install Necessary SDKs
For Python development, you'll need to install the Google Gen AI SDK. You can install it using pip:
pip install -U google-genaiIf you plan to integrate with specific real-time communication platforms like LiveKit, you might need additional libraries:
pip install "livekit-agents[google]~=1.0"Configure Environment Variables
Set up environment variables to securely manage your API key. For the Google Gemini API, you would typically set:
GOOGLE_API_KEY: Your Gemini API key.
If using Vertex AI, you might need to set GOOGLE_APPLICATION_CREDENTIALS to the path of your service account key file.
Understanding the Gemini Live API Architecture
The Gemini Live API is designed for dynamic, ongoing interactions. Here are its core architectural aspects:
WebSocket-Based Sessions
The API operates over WebSocket connections. A WebSocket establishes a persistent, bidirectional communication channel between your application (client/server) and the Gemini server. This allows for continuous streaming of data in both directions, which is essential for real-time interactions.
Stateful Interactions
Sessions with the Live API are stateful. This means the API can maintain context throughout an interaction. For example, it can remember previous parts of a conversation or information from earlier in a video stream. The default maximum context length for a session is 32,768 tokens. This context is allocated to store real-time data (e.g., 25 tokens per second for audio, 258 tokens per second for video) as well as text inputs and model outputs.
Server-Side Authentication
The Live API primarily supports server-to-server authentication. This is a critical security consideration, meaning you should call the API from your backend application rather than directly from client-side code (like a web browser) to protect your API key and manage requests securely.
Core Workflow: Interacting with the Live API
The general process for using the Gemini Live API involves these steps:
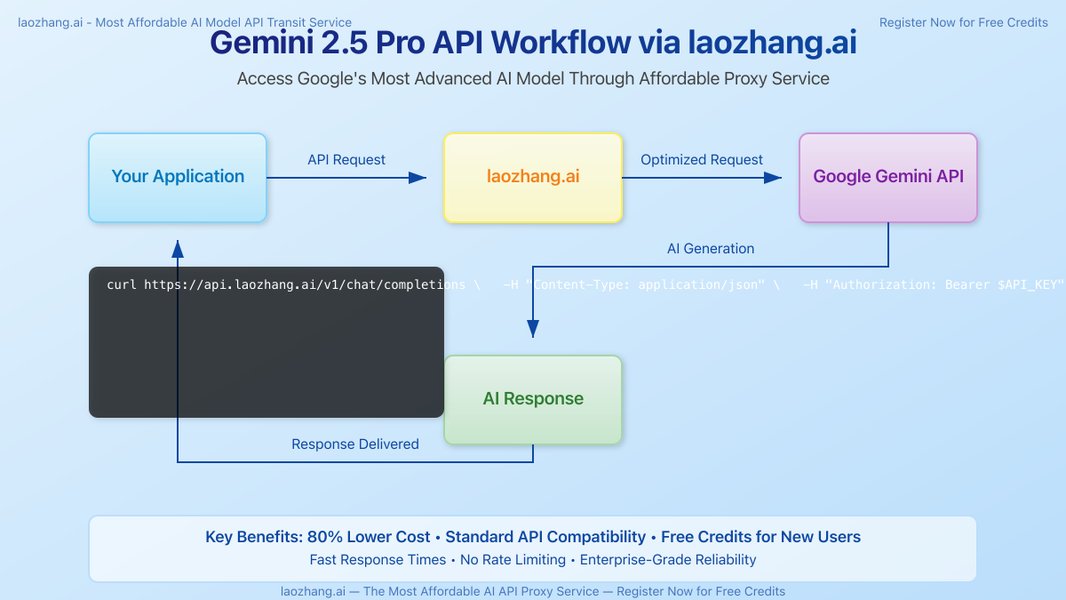
A conceptual overview of an API interaction workflow.
- Authenticate: Ensure your application can authenticate with the API using your API key.
- Establish Connection: Open a WebSocket connection to the Gemini Live API endpoint. This initiates a session.
- Configure Session: Specify parameters for the session, such as the model to use and the desired response modalities (e.g., text, audio).
- Send Input: Stream multimodal input to the API. This can include:
- Text messages or prompts.
- Live audio streams (e.g., from a microphone).
- Live video streams (e.g., from a camera).
- Receive Output: Asynchronously receive responses from the API. These can be:
- Text responses.
- Synthesized audio replies.
- Manage Session: Handle the lifecycle of the session, including continuing the interaction and eventually closing the connection when done. The API supports session resumption for up to 24 hours in case of temporary network disruptions, using
session_resumptionhandles.
Python Code Example (Conceptual)
Here’s a conceptual Python snippet using asyncio to demonstrate connecting and interacting with the Gemini Live API. Note that specific model names and configurations should be checked against the latest official documentation.
import asyncio import google.generativeai as genai # Configure your API key # genai.configure(api_key="YOUR_GEMINI_API_KEY") # Or ensure GOOGLE_API_KEY is set in your environment async def run_live_session(): # Ensure GOOGLE_API_KEY is set in your environment variables # Or configure it directly: genai.configure(api_key="YOUR_API_KEY") # Example model, check official documentation for current live models model_name = "gemini-1.5-flash-latest" # Using a common model, specific "live" models might differ # Configuration for the live session # This is a simplified config; refer to docs for LiveConnectConfig specifics if available in the SDK path you use # For direct WebSocket, you'd manage this as part of the connection setup. # The <code>google-genaiSDK'sGenerativeModel.generate_content(stream=True)provides streaming, # but dedicated "Live API" WebSocket interactions might use a different client or setup. # The example below is more akin to general streaming. For a true Live API WebSocket client, # refer to specific Live API client libraries or direct WebSocket implementation. print(f"Attempting to use model: {model_name}") model = genai.GenerativeModel(model_name) # For true Live API with WebSockets, the connection setup would be different. # The following simulates a chat-like streaming interaction. chat = model.start_chat(history=[]) print("Live session started. Type 'exit' to end.") while True: user_input = input("User> ") if user_input.lower() == "exit": print("Exiting session.") break try: # Send message and stream response # For Live API, this would besession.send_client_contentresponse_stream = chat.send_message(user_input, stream=True) print("Gemini> ", end="") for chunk in response_stream: print(chunk.text, end="", flush=True) print() # Newline after full response except Exception as e: print(f"An error occurred: {e}") break if __name__ == "__main__": try: asyncio.run(run_live_session()) except KeyboardInterrupt: print("\nSession interrupted by user.")
Note: The code above is a general representation. For specific Gemini Live API WebSocket usage, refer to official Google AI SDK documentation and examples for client.aio.live.connect or similar WebSocket-specific functionalities if available, or direct WebSocket implementation patterns. The google-genai SDK evolves, so always check the latest guides. Answer D provided a more direct client.aio.live.connect example which is more aligned with the Live API's WebSocket nature.
Key Features and Capabilities
The Gemini Live API is packed with features designed for sophisticated real-time applications:
Multimodal Processing
The API shines in its ability to understand and respond to multiple types of input simultaneously.
- Inputs: Text, continuous audio streams, and video feeds.
- Outputs: Text and synthesized audio. For audio output, it utilizes Google's Chirp 3 technology, offering 8 HD voices across 31 languages. This can be configured via
LiveConnectConfig.
Real-Time Interaction and Low Latency
Built for speed, the API minimizes delays, making conversations feel natural. Users can even interrupt the model's responses mid-stream, and the API can adapt, contributing to a more human-like conversational flow.
Session Management and Context
- Context Length: Sessions can maintain a context of up to 32,768 tokens by default.
- Session Resumption: Provides handles (
session_resumption) to reconnect and resume sessions within 24 hours if temporary network disruptions occur, preserving the interaction state.
Platforms and Integration
- Availability: You can access and prototype with the Live API via Google AI Studio and Google Cloud Vertex AI.
- Partner Integrations: For easier integration into web and mobile apps, Google recommends using solutions from partners like Daily or LiveKit.
Understanding Gemini Live API Performance Aspects
The following chart offers a conceptual look at key performance and capability aspects of the Gemini Live API. These are illustrative values based on its described features, not hard data points, to give a sense of its strengths.
Conceptual performance aspects of the Gemini Live API.
Supported Modalities and Configuration
The table below summarizes the input/output capabilities and key configuration aspects of the Gemini Live API:
| Feature Aspect | Input Modalities Supported | Output Modalities Supported | Key Configuration Parameters (Illustrative) |
|---|---|---|---|
| Core Interaction | Text, Audio (stream), Video (stream) | Text, Audio (synthesized speech) | model (e.g., 'gemini-2.0-flash-live-001'), response_modalities (e.g., ["AUDIO", "TEXT"]) |
| Audio Output | N/A | Synthesized speech via Chirp 3 | speech_config (within LiveConnectConfig), voice_config, language_code |
| Session Context | Implicitly managed through session | N/A | Up to 32,768 tokens by default, session resumption handles |
| Real-time Data Rates | Audio: ~25 tokens/sec, Video: ~258 tokens/sec | N/A | Managed by API based on stream |
Visualizing the Gemini Live API Workflow
This mindmap outlines the key components and steps involved in utilizing the Google Gemini Live API, from initial setup to real-time interaction and leveraging its core features.
Tutorial: Gemini 2.0 Multimodal Live Streaming
For a practical demonstration of how to integrate Google's Gemini 2.0 multimodal live streaming capabilities, the following video provides a tutorial using Google AI Studio. It showcases how to build applications with these real-time features, offering valuable insights into its potential.
This video tutorial is relevant as it visually walks through setting up and using the live streaming API, which is central to the Gemini Live API's functionality. It helps in understanding how to harness its multimodal capabilities in a development environment like Google AI Studio, which is a recommended starting point for experimentation.
Important Considerations and Best Practices
- Preview Status: As of its latest updates, the Gemini Live API may be in a preview stage. This means functionalities could change, and it might not be recommended for all production use cases without careful evaluation. Always refer to the official documentation for the current status.
- Security: Prioritize server-side implementation for the Live API. Avoid exposing API keys directly in client-side applications.
- Error Handling: Implement robust error handling for WebSocket connections, API responses, and potential stream interruptions.
- Rate Limits and Quotas: Be mindful of API rate limits, token limits per session (e.g., 32,768), and processing rates for audio/video to prevent service disruptions.
- Testing: Utilize Google AI Studio or Vertex AI Studio for initial testing and prototyping before full-scale deployment.
- Documentation: The Gemini API and its features are continuously evolving. Always consult the official Google AI and Google Cloud documentation for the most up-to-date information, model names, and SDK usage.
Frequently Asked Questions (FAQ)
What is the Google Gemini Live API?
The Google Gemini Live API is a stateful API that enables real-time, bidirectional interactions with Gemini models. It uses WebSockets to support low-latency streaming of multimodal inputs (text, audio, video) and can generate text and synthesized audio outputs. It's designed for applications requiring natural, human-like conversations and live data processing.
Is the Gemini Live API free to use?
Usage of the Gemini Live API, like other Google Cloud services, is typically subject to pricing based on factors such as the volume of data processed, the specific models used, and the duration of sessions. While there might be free tiers or trial credits available through Google Cloud or Google AI Studio, extensive or production usage will likely incur costs. Always check the official Google Cloud pricing pages for the most current information.
What are the main use cases for the Live API?
The Live API is ideal for applications requiring real-time conversational AI, such as:
- Advanced voice assistants and chatbots capable of natural turn-taking.
- Interactive customer support agents.
- Real-time transcription and translation services with voice output.
- Live video analysis combined with interactive voice feedback.
- Educational tools offering interactive tutoring.
- Immersive gaming experiences with responsive AI characters.
Can I use the Gemini Live API directly from a web browser?
While you can use the Google AI JavaScript SDK for prototyping client-side web applications with some Gemini API features, the Gemini Live API specifically is recommended for server-to-server authentication and use. This is primarily for security reasons, to protect your API key and manage interactions robustly from a backend. For web and mobile apps, Google often suggests using integrations from partners like Daily to facilitate client-side real-time communication that then interacts with a secure backend leveraging the Live API.
Recommended Further Exploration
- Learn advanced techniques for managing Google Gemini Live API sessions and context.
- Discover how to integrate Google Gemini Live API with LiveKit for building real-time video applications.
- Explore best practices for handling audio streams and ensuring low latency with the Google Gemini Live API.
- Compare the Google Gemini Live API with other real-time conversational AI services for multimodal interactions.
References
Last updated May 11, 2025