
Unlocking Resilience and Scale: A Deep Dive into Distributed System Design Patterns
Mastering the architectural blueprints that power today's most robust and scalable applications.
Key Insights into Distributed System Patterns
- Proven Solutions: Distributed system design patterns offer time-tested, reusable solutions to common challenges in building applications that span multiple machines or data centers, such as achieving scalability, fault tolerance, and high availability.
- Strategic Trade-offs: Selecting and implementing these patterns involves understanding fundamental trade-offs, notably those described by the CAP theorem (Consistency, Availability, Partition tolerance), guiding architects to prioritize based on specific application needs.
- Synergistic Application: Robust distributed systems often leverage a combination of multiple patterns, working synergistically to address diverse aspects like communication, data management, error handling, and load distribution.
Distributed systems, by their very nature, introduce complexities related to concurrency, partial failures, network latency, and data consistency across multiple nodes. Design patterns in this domain serve as a crucial toolkit for architects and developers. They encapsulate best practices and architectural wisdom, enabling the creation of systems that are not only performant and scalable but also resilient to failures and easier to maintain and evolve. This exploration delves into various categories of these patterns, highlighting their purpose, benefits, and common applications in building sophisticated distributed architectures.
Visualizing Interconnected Services
Many distributed system patterns find their application in microservices architectures, where applications are broken down into smaller, independently deployable services. The image below illustrates a conceptual microservices layout, where patterns for communication, data management, and resilience become essential for effective operation.
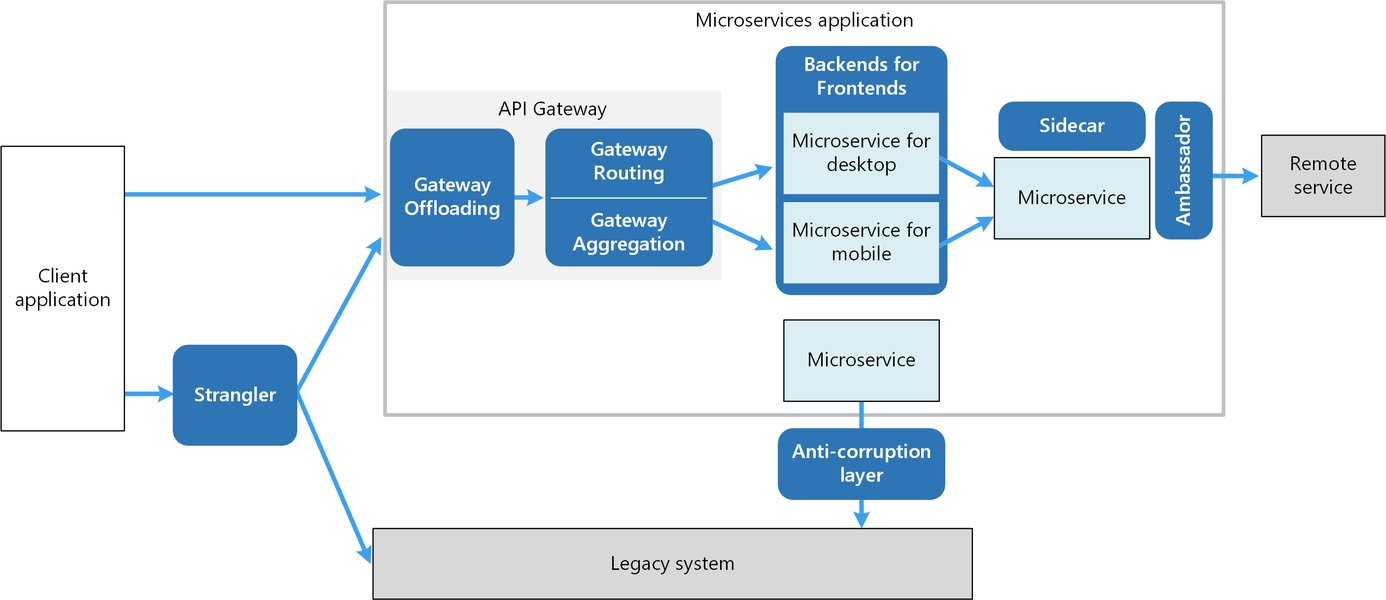
A visual representation of interconnected microservices, a common context for applying distributed system design patterns.
Core Categories of Distributed System Design Patterns
Distributed system design patterns can be broadly categorized based on the problems they solve. Understanding these categories helps in selecting appropriate patterns for specific architectural challenges.
Communication Patterns
These patterns govern how different components or services in a distributed system exchange information efficiently and reliably.
Publish-Subscribe (Pub-Sub)
Purpose: Enables asynchronous communication where message senders (publishers) do not directly send messages to specific receivers (subscribers). Instead, messages are published to channels or topics, and subscribers interested in those topics receive the messages.
Benefits:
- Decouples publishers from subscribers, allowing them to evolve independently.
- Enhances scalability as new subscribers can be added without affecting publishers.
- Improves resilience by allowing messages to be queued if subscribers are temporarily unavailable.
- Supports event-driven architectures.
Considerations: Requires a message broker, which can become a bottleneck or single point of failure if not designed for high availability. Message ordering and delivery guarantees can vary.
Common Use Cases: Real-time notifications (e.g., social media updates, news feeds), event streaming in IoT applications, decoupling microservices, distributing tasks to worker processes.
API Gateway
Purpose: Provides a single, unified entry point for all client requests to access various backend services in a microservices architecture or distributed system.
Benefits:
- Simplifies client interaction by abstracting backend service complexity.
- Centralizes cross-cutting concerns like authentication, authorization, rate limiting, and logging.
- Enables request routing, composition, and protocol translation.
- Can provide optimized APIs for specific client types (e.g., mobile vs. web).
Considerations: Can become a bottleneck if not scaled properly. Adds an extra network hop, potentially increasing latency. Requires careful design to avoid becoming overly complex (a "god" component).
Common Use Cases: Microservice-based applications, mobile backends, providing a secure and managed access layer to internal services.
Ambassador Pattern
Purpose: Acts as a helper or proxy that sits alongside a service, offloading common connectivity tasks such as retries, circuit breaking, monitoring, and secure communication (TLS termination) for outbound connections to other services or external resources.
Benefits:
- Simplifies the main application code by abstracting network-related complexities.
- Allows for language-agnostic implementation of common communication features.
- Facilitates standardized handling of interactions with remote services.
Considerations: Adds a small amount of latency due to the extra hop. Increases the number of deployed components.
Common Use Cases: Inter-service communication in microservices, managing connections to legacy systems or external APIs, implementing service mesh functionalities at a local level.
Fault Tolerance and Resilience Patterns
These patterns are designed to help systems withstand and gracefully recover from failures, ensuring high availability and preventing cascading failures.
Circuit Breaker
Purpose: Prevents an application from repeatedly trying to execute an operation that is likely to fail. After a configured number of failures, the circuit "opens," and subsequent calls fail immediately or return a default response, without attempting the failing operation.
Benefits:
- Prevents cascading failures by isolating failing services.
- Allows failing services time to recover by reducing their load.
- Provides fast failure feedback to clients.
- Improves overall system stability and resilience.
Considerations: Requires careful tuning of thresholds for opening and closing the circuit. The "half-open" state (allowing a limited number of test requests) needs robust implementation.
Common Use Cases: Protecting applications from failures in calls to remote microservices, third-party APIs, or databases. Essential in microservice architectures.
Bulkhead
Purpose: Isolates elements of an application into pools so that if one fails, the others will continue to function. It's analogous to the compartments in a ship's hull; if one compartment is breached, the ship doesn't sink.
Benefits:
- Prevents cascading failures by containing faults within specific components or resource pools.
- Improves system resilience by ensuring that a failure in one part of the system doesn't exhaust resources needed by other parts.
- Allows for tailored resource allocation for different parts of an application.
Considerations: Can increase complexity in resource management and configuration. Determining the right size and scope for bulkheads can be challenging.
Common Use Cases: Isolating resource pools (e.g., connection pools, thread pools) for different services or features, multi-tenant applications to isolate tenants, protecting critical system components from non-critical ones.
Data Management and Consistency Patterns
Managing data across multiple nodes while ensuring consistency, availability, and scalability is a core challenge. These patterns offer solutions.
Sharding (Data Partitioning)
Purpose: Divides a large dataset horizontally into smaller, more manageable pieces called shards. Each shard is stored on a separate database server or node.
Benefits:
- Improves horizontal scalability by distributing data and load across multiple servers.
- Enhances performance by reducing the amount of data each server has to manage and query.
- Increases availability, as the failure of one shard doesn't necessarily make the entire dataset unavailable (depending on replication).
Considerations: Adds complexity to data access logic (routing queries to the correct shard). Cross-shard transactions and joins can be difficult. Re-sharding (changing the number of shards or distribution) can be complex. Choosing an appropriate sharding key is critical.
Common Use Cases: Large-scale databases (e.g., user profiles, product catalogs), systems with high write throughput, geo-distributed applications to store data closer to users.
Event Sourcing
Purpose: Captures all changes to an application's state as a sequence of immutable events. Instead of storing the current state directly, the system stores the history of events that led to the current state.
Benefits:
- Provides a full audit trail of all changes, enabling historical queries and debugging.
- Allows reconstruction of past states and facilitates temporal queries ("what was the state at this point in time?").
- Can simplify business logic in complex domains by focusing on events.
- Enables deriving multiple read models (projections) optimized for different query needs.
Considerations: Can lead to a large volume of event data. Replaying events to reconstruct state can be time-consuming for very long event streams. Querying current state might require processing events or maintaining separate read models (often used with CQRS).
Common Use Cases: Financial systems (tracking transactions), e-commerce (order history), collaborative applications, systems requiring strong auditability and versioning.
Command Query Responsibility Segregation (CQRS)
Purpose: Separates the model for updating data (commands) from the model for reading data (queries). This means using different data structures and potentially different data stores for write operations and read operations.
Benefits:
- Allows independent scaling of read and write workloads.
- Optimizes data models for specific tasks: write models for consistency, read models for query performance. * Can improve security by restricting which operations users can perform.
- Often used with Event Sourcing, where events update the write model, and projections create various read models.
Considerations: Increases system complexity due to separate models and potential data synchronization needs between write and read stores (eventual consistency is common).
Common Use Cases: High-traffic applications with distinct read/write patterns, systems with complex querying requirements, collaborative domains, applications using Event Sourcing.
Saga Pattern
Purpose: Manages long-running transactions that span multiple services in a distributed system. Since distributed transactions (like two-phase commit) are often complex and can reduce availability, Sagas use a sequence of local transactions. If a local transaction fails, compensating transactions are executed to undo preceding work.
Benefits:
- Achieves eventual consistency across services without requiring distributed locks or tight coupling.
- Improves availability as services can complete their local transactions independently.
- Each service owns its data and local transaction.
Considerations: Debugging and reasoning about Sagas can be complex due to their asynchronous nature and compensating logic. Compensating transactions must be carefully designed to be idempotent and reliable.
Common Use Cases: Order processing in e-commerce (order, payment, inventory, shipping), trip booking systems, any business process involving multiple independent microservices that need to coordinate.
Scalability and Load Distribution Patterns
These patterns focus on enabling systems to handle increasing amounts of work and distributing that work efficiently across available resources.
Load Balancing
Purpose: Distributes incoming network traffic or computational workload across multiple servers or resources to prevent any single resource from being overwhelmed.
Benefits:
- Improves application responsiveness and availability.
- Increases scalability by allowing easy addition of more servers to the pool.
- Enhances fault tolerance by redirecting traffic away from failed or unhealthy servers.
Considerations: The load balancer itself can become a single point of failure if not made redundant. Different load balancing algorithms (round-robin, least connections, etc.) suit different scenarios. Session persistence can be a challenge for stateful applications.
Common Use Cases: Web server farms, application server clusters, distributing tasks to worker nodes, database read replicas.
Coordination Patterns
In a distributed system, tasks often need to be coordinated across multiple nodes to ensure consistency or elect a leader for specific responsibilities.
Leader Election
Purpose: Designates a single process or node from a group as the "leader," responsible for coordinating certain tasks or managing a shared resource. If the leader fails, the remaining nodes elect a new leader.
Benefits:
- Simplifies the design of certain distributed algorithms by having a single point of coordination.
- Ensures that critical operations are performed by only one node at a time, preventing conflicts.
- Facilitates consistent decision-making in a distributed environment.
Considerations: The election process itself can be complex and must be fault-tolerant. Detecting leader failure and initiating re-election can introduce latency.
Common Use Cases: Managing distributed locks, coordinating distributed transactions (though Sagas are often preferred), task scheduling in a cluster, maintaining metadata in distributed storage systems (e.g., Apache ZooKeeper, etcd).
Deployment and Architectural Support Patterns
These patterns relate to how components are deployed and how they interact with their environment, often supporting other patterns.
Sidecar
Purpose: Deploys auxiliary components alongside a primary application container or process. The sidecar shares the same lifecycle and network namespace as the main application, providing supporting functionalities.
Benefits:
- Offloads cross-cutting concerns like logging, monitoring, configuration management, and network proxying from the main application.
- Promotes modularity and separation of concerns.
- Allows different technologies to be used for the main application and its sidecars.
- Facilitates reuse of common functionalities across multiple services.
Considerations: Increases the number of deployed components per application instance, potentially increasing resource consumption. Requires orchestration platform support (e.g., Kubernetes Pods).
Common Use Cases: Service mesh proxies (like Envoy or Linkerd), log aggregators, configuration watchers, health check monitors.
Mapping Pattern Relationships: A Mindmap View
The following mindmap provides a conceptual overview of how various distributed system design patterns are categorized and interconnected, offering a visual guide to their roles within a distributed architecture. Understanding these relationships helps in composing patterns to build robust systems.
This mindmap illustrates primary categories such as Communication, Data Management, Fault Tolerance, Scalability, Coordination, and Deployment Support, with key patterns listed under each. It shows how patterns like Sharding can influence Scalability, or how architectural choices like Microservices often rely on multiple patterns from different categories.
Comparative Analysis of Key Patterns
Different distributed system patterns offer varying strengths across several architectural dimensions. The radar chart below provides a comparative, opinionated analysis of five selected patterns against criteria such as their contribution to horizontal scalability, fault tolerance, ease of implementation, decoupling strength, and operational simplicity. The scale is 1 (lower) to 10 (higher), with values always greater than 1. "Ease of Implementation" and "Operational Simplicity" mean higher scores are better (less complex/easier).
This chart highlights that patterns like Sharding excel in Horizontal Scalability but can be complex to implement and operate. Conversely, Circuit Breaker significantly boosts Fault Tolerance with moderate implementation ease. Pub-Sub shines in Decoupling Strength. Such comparisons aid in pattern selection based on prioritized system characteristics.
Summary Table of Common Distributed System Patterns
The following table provides a concise summary of several widely used distributed system design patterns, outlining their primary goals, key benefits, and typical use cases. This serves as a quick reference for understanding the core purpose of each pattern.
| Pattern | Primary Goal(s) | Key Benefits | Common Use Cases |
|---|---|---|---|
| Publish-Subscribe (Pub-Sub) | Decoupling, Asynchronous Communication | Scalability, Resilience, Flexibility, Event-driven | Real-time notifications, Event-driven systems, Microservice integration |
| Circuit Breaker | Fault Tolerance, Prevent Cascading Failures | System stability, Fast failure detection, Graceful degradation | Microservice calls, External API integrations, Database connections |
| Sharding (Partitioning) | Data Scalability, Performance Optimization | Horizontal scaling for data, Reduced query latency, Improved write throughput | Large databases, Geo-distributed data, High-traffic applications |
| Event Sourcing | State Management, Auditability, Temporal Queries | Full history of changes, Reconstruct state, Debuggability, Enables CQRS | Financial systems, Audit logs, E-commerce order history, Collaborative tools |
| CQRS (Command Query Responsibility Segregation) | Optimize Read/Write Operations, Scalability | Independent scaling of read/write paths, Optimized data models for each path | High-traffic systems with different read/write loads, Complex query needs |
| Leader Election | Coordination, Consistent Decision Making | Single point of authority for specific tasks, Prevents conflicts | Distributed locks, Task scheduling, Master-node selection in clusters |
| Sidecar | Offload Operational Concerns, Modularity | Decouples application logic from infrastructure concerns, Reusability | Logging, Monitoring, Security, Service mesh proxies (e.g., Envoy) |
| API Gateway | Centralized Access, Request Routing, Security | Simplified client interaction, Centralized cross-cutting concerns (auth, rate limiting) | Microservices backends, Mobile application APIs, Exposing services externally |
| Bulkhead | Fault Isolation, Resource Protection | Prevents cascading failures, Protects critical components from overload | Multi-tenant systems, Isolating resource pools (threads, connections) |
| Saga | Manage Distributed Transactions, Eventual Consistency | Maintains data consistency across services without distributed locks | Order processing, Booking systems, Long-running business processes |
Video Overview: Top Distributed System Patterns
For a concise visual and auditory explanation of some of the most frequently used distributed system patterns, the following video offers valuable insights. It covers several key patterns, explaining their purpose and how they help in building robust systems.
This video, "Top 7 Most-Used Distributed System Patterns," provides a good overview that complements the detailed explanations in this deep dive. It's helpful for understanding how patterns like Load Balancer, Circuit Breaker, and Sharding are applied in practice.
Best Practices for Applying Distributed System Patterns
Successfully implementing these patterns requires adherence to certain best practices:
- Design for Failure: Assume that components will fail. Build systems with redundancy, retries (with exponential backoff and jitter), and graceful degradation in mind. Patterns like Circuit Breaker and Bulkhead are central to this.
- Embrace Loose Coupling: Minimize dependencies between services. Asynchronous communication (e.g., via Pub-Sub) and well-defined interfaces (e.g., through an API Gateway) help achieve this, making systems more resilient and easier to evolve.
- Strive for Idempotency: Design operations, especially those involved in Sagas or retries, so that making the same call multiple times has the same effect as making it once. This is crucial for handling transient network issues or message redeliveries.
- Prioritize Observability: Implement comprehensive logging, metrics, and distributed tracing. Understanding the flow of requests and the state of components is vital for debugging and operating distributed systems. Patterns like Sidecar can help centralize telemetry collection.
- Understand CAP Theorem Trade-offs: Be conscious of the trade-offs between Consistency, Availability, and Partition tolerance. Different patterns and system requirements will lead to different choices (e.g., eventual consistency in Sagas vs. stronger consistency in some Leader Election scenarios).
- Favor Statelessness: Design services to be stateless whenever possible. This simplifies scaling, load balancing, and recovery from failures, as any instance can handle any request. State, if needed, can be externalized to a distributed cache or database.
- Utilize Asynchronous Processing: For long-running operations or to improve responsiveness, use asynchronous patterns like Pub-Sub or message queues. This helps to decouple components and absorb load spikes.
Frequently Asked Questions (FAQ)
What is the main goal of distributed system design patterns?
The primary goal of distributed system design patterns is to provide proven, reusable solutions to common problems encountered when building systems that are spread across multiple computers or nodes. These problems often relate to scalability (handling more users/data), fault tolerance (continuing to operate despite failures), consistency (ensuring data is correct across nodes), communication (how services talk to each other), and maintainability (making the system easier to understand and change).
How do I choose the right design pattern for my system?
Choosing the right pattern depends on several factors:
- Specific Problem: Identify the precise challenge you're trying to solve (e.g., preventing cascading failures suggests Circuit Breaker; scaling data suggests Sharding).
- System Requirements: Consider non-functional requirements like desired levels of availability, consistency (CAP theorem), latency, and throughput.
- Existing Infrastructure: Your current technology stack and platform (e.g., cloud provider services, container orchestration) might favor certain patterns.
- Team Expertise: The complexity of implementing and managing a pattern should align with your team's skills.
- Trade-offs: Every pattern has trade-offs. For example, CQRS can improve read performance but adds complexity. Understand these before committing.
Can I combine multiple distributed system design patterns?
Yes, absolutely. In fact, it's very common and often necessary to combine multiple patterns to build a robust distributed system. For example, a microservices architecture might use:
- An API Gateway for client entry.
- Load Balancing to distribute requests to service instances.
- Circuit Breakers for inter-service calls.
- Publish-Subscribe for asynchronous event-driven communication.
- Sharding for data storage in some services.
- Sidecars for observability and network control.
What is the CAP theorem, and how does it relate to these patterns?
The CAP theorem (Consistency, Availability, Partition tolerance) states that a distributed data store can only provide two of these three guarantees simultaneously in the event of a network partition.
- Consistency: All nodes see the same data at the same time.
- Availability: Every request receives a (non-error) response, without guarantee that it contains the most recent write.
- Partition Tolerance: The system continues to operate despite an arbitrary number of messages being dropped (or delayed) by the network between nodes.
Recommended Further Exploration
- How do specific cloud platforms like AWS or Azure implement common distributed system patterns?
- What are the performance implications of choosing Event Sourcing with CQRS versus traditional CRUD approaches?
- Explore real-world case studies of companies successfully applying the Saga pattern for distributed transactions.
- What are anti-patterns to avoid when designing distributed systems?
References

Last updated May 6, 2025